
search
Cut training costs and accelerate model tuning with advanced search strategies.
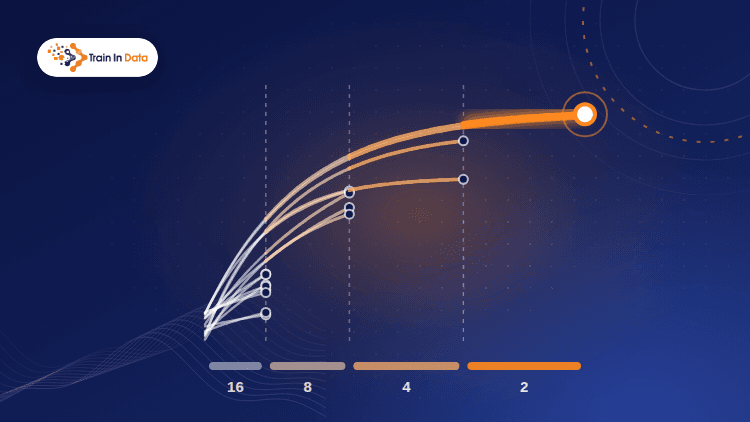
This course explores multi-fidelity optimization techniques designed to reduce the computational cost of hyperparameter tuning by balancing low-fidelity approximations with high-fidelity evaluations. It covers the mechanics of Successive Halving, Hyperband, and Asynchronous Successive Halving, providing insights into how these algorithms efficiently navigate hyperparameter spaces. The material details practical implementation strategies using scikit-learn, including budget allocation, resource management, and the trade-offs between exploration and exploitation. Learners will gain an understanding of how to optimize model performance within strict time and resource constraints.
Topics Covered:
Data Scientist | Python Developer | Author and Instructor
I'm a data scientist, machine learning educator and open-source developer. I've built machine learning models for credit risk, insurance claims and fraud prevention, and I am passionate about helping data scientists build models that hold up in real-world projects. My courses are designed for intermediate and advanced practitioners. They cover feature engineering, feature selection, hyperparameter optimization, imbalanced data and the design of robust machine learning pipelines, with a strong emphasis on techniques you can apply straight away in your own work. In the age of generative AI, when a working model can be coded in minutes, the real skill lies in understanding the methods deeply enough to review that output with rigor and a critical eye, and that's exactly what these courses are built to develop. I'm the creator and maintainer of Feature-engine, an open-source Python library for feature engineering and feature selection used by data scientists worldwide. I'm also the author of three books published by Packt: Python Feature Engineering Cookbook, Feature Selection in Machine Learning, and Imbalanced Data: Myths, Mistakes and Modern Solutions. I speak regularly at conferences and meetups, and I enjoy connecting technical communities with the tools and knowledge they need to succeed. In 2018 I received a Data Science Leaders Award, and in 2019 LinkedIn recognized me as one of its voices in data science and analytics. Before moving into data science, I earned an MSc in Biology and a PhD in Biochemistry, then spent more than eight years as a research scientist at institutions including University College London and the Max Planck Institute. That scientific training still shapes how I teach: rigorous, evidence-based, and focused on understanding why a method works before reaching for it.